

Humans vote,
AI gets ranked
Some things only people can judge, like whether a voice sounds natural or an avatar feels real. Watch two anonymous outputs from the same prompt and pick the better one. The models are revealed after you vote.
- Votes cast
- 2,000+
- Models benchmarked
- 25+
- Arenas
- 3
HyperFrames+ Opus 5.5
1060plus or minus 46Wins 30–60 second films
Remotion+ Opus 5.5
1053plus or minus 40Wins films over a minute
Remotion+ Sonnet 5.5
1026plus or minus 48Top entry on Sonnet 5.5

Avatar Arena Leaderboard: Personal
| Rank | Provider | elo | 95% CI | Interval | Votes |
|---|---|---|---|---|---|
| 1 | HeyGenAvatar 6 | 1,197 | 1162 to 1241 | plus or minus 40 | 542 |
| 2 | CreatifyAurora 2.0 | 1,053 | 1008 to 1111 | plus or minus 52 | 133 |
| 3 | VEEDLipsync 2.0 | 1,000 | 943 to 1051 | plus or minus 54 | 127 |
| 4 | CaptionsAvatar X | 896 | 829 to 955 | plus or minus 63 | 163 |
| 5 | RunwayGWM-1 Avatars | 854 | 743 to 935 | plus or minus 96 | 119 |
Personal track: each person uploads a video of themselves, and both providers use that footage to make a new video of them reading the same script. Based on 542 blind votes, 27 Oct – 16 Nov 2026. Bradley–Terry scores on an Elo scale, where 1000 is the average for this track, with 95% ranges from 1,000 bootstrap resamples of voters. A tie or “both bad” vote contributes half a point to each side. Every rival faces HeyGen; comparisons between rivals are indirect. The report assesses uncertainty in score differences. Data through 16 Nov 2026, excluding known internal accounts.
Methodology
How a vote becomes a rank


Blind by default
You see two outputs, never two names. Models are revealed only after you vote, so brand can't sway the result.

Same conditions
Both sides get the same prompt, inputs and budget. We test the system as it ships: model, harness and settings together.

Real prompts
Prompts come from the people voting, so each arena tests what people actually want to make, not a fixed list to tune against.

Honest choices
Pick A, pick B, call a tie or say both are bad. A vote never has to crown a winner that didn't earn it.

Ranking
Every head-to-head vote feeds a Bradley–Terry model, shown on an Elo scale where 1000 is average.

Uncertainty
Every score comes with a 95% range. When ranges overlap we call it a tie, not a win.
Video Arena Leaderboard
read the full report →| Rank | Harness | elo | 95% CI | Interval | Writes in |
|---|---|---|---|---|---|
| 1 | HyperFramesOpus 5.5 | 1,060 | 1008 to 1100 | plus or minus 46 | HTML + GSAP |
| 2 | RemotionOpus 5.5 | 1,053 | 1014 to 1094 | plus or minus 40 | React |
| 3 | RemotionSonnet 5.5 | 1,026 | 979 to 1074 | plus or minus 48 | React |
| 4 | HyperFramesSonnet 5.5 | 975 | 926 to 1022 | plus or minus 48 | HTML + GSAP |
| 5 | MotionMosaic | 885 | 833 to 937 | plus or minus 52 | End to end |
Bradley–Terry scores on an Elo scale, where 1000 is average, with 95% bootstrap ranges. Based on 193 decided blind votes, 30 Sep – 16 Oct 2026. Overlapping ranges mean the entries are statistically tied. Updated 16 Oct 2026.
Video Arena

00:01.2 / 00:06.0
00:01.2 / 00:06.0
Prompt
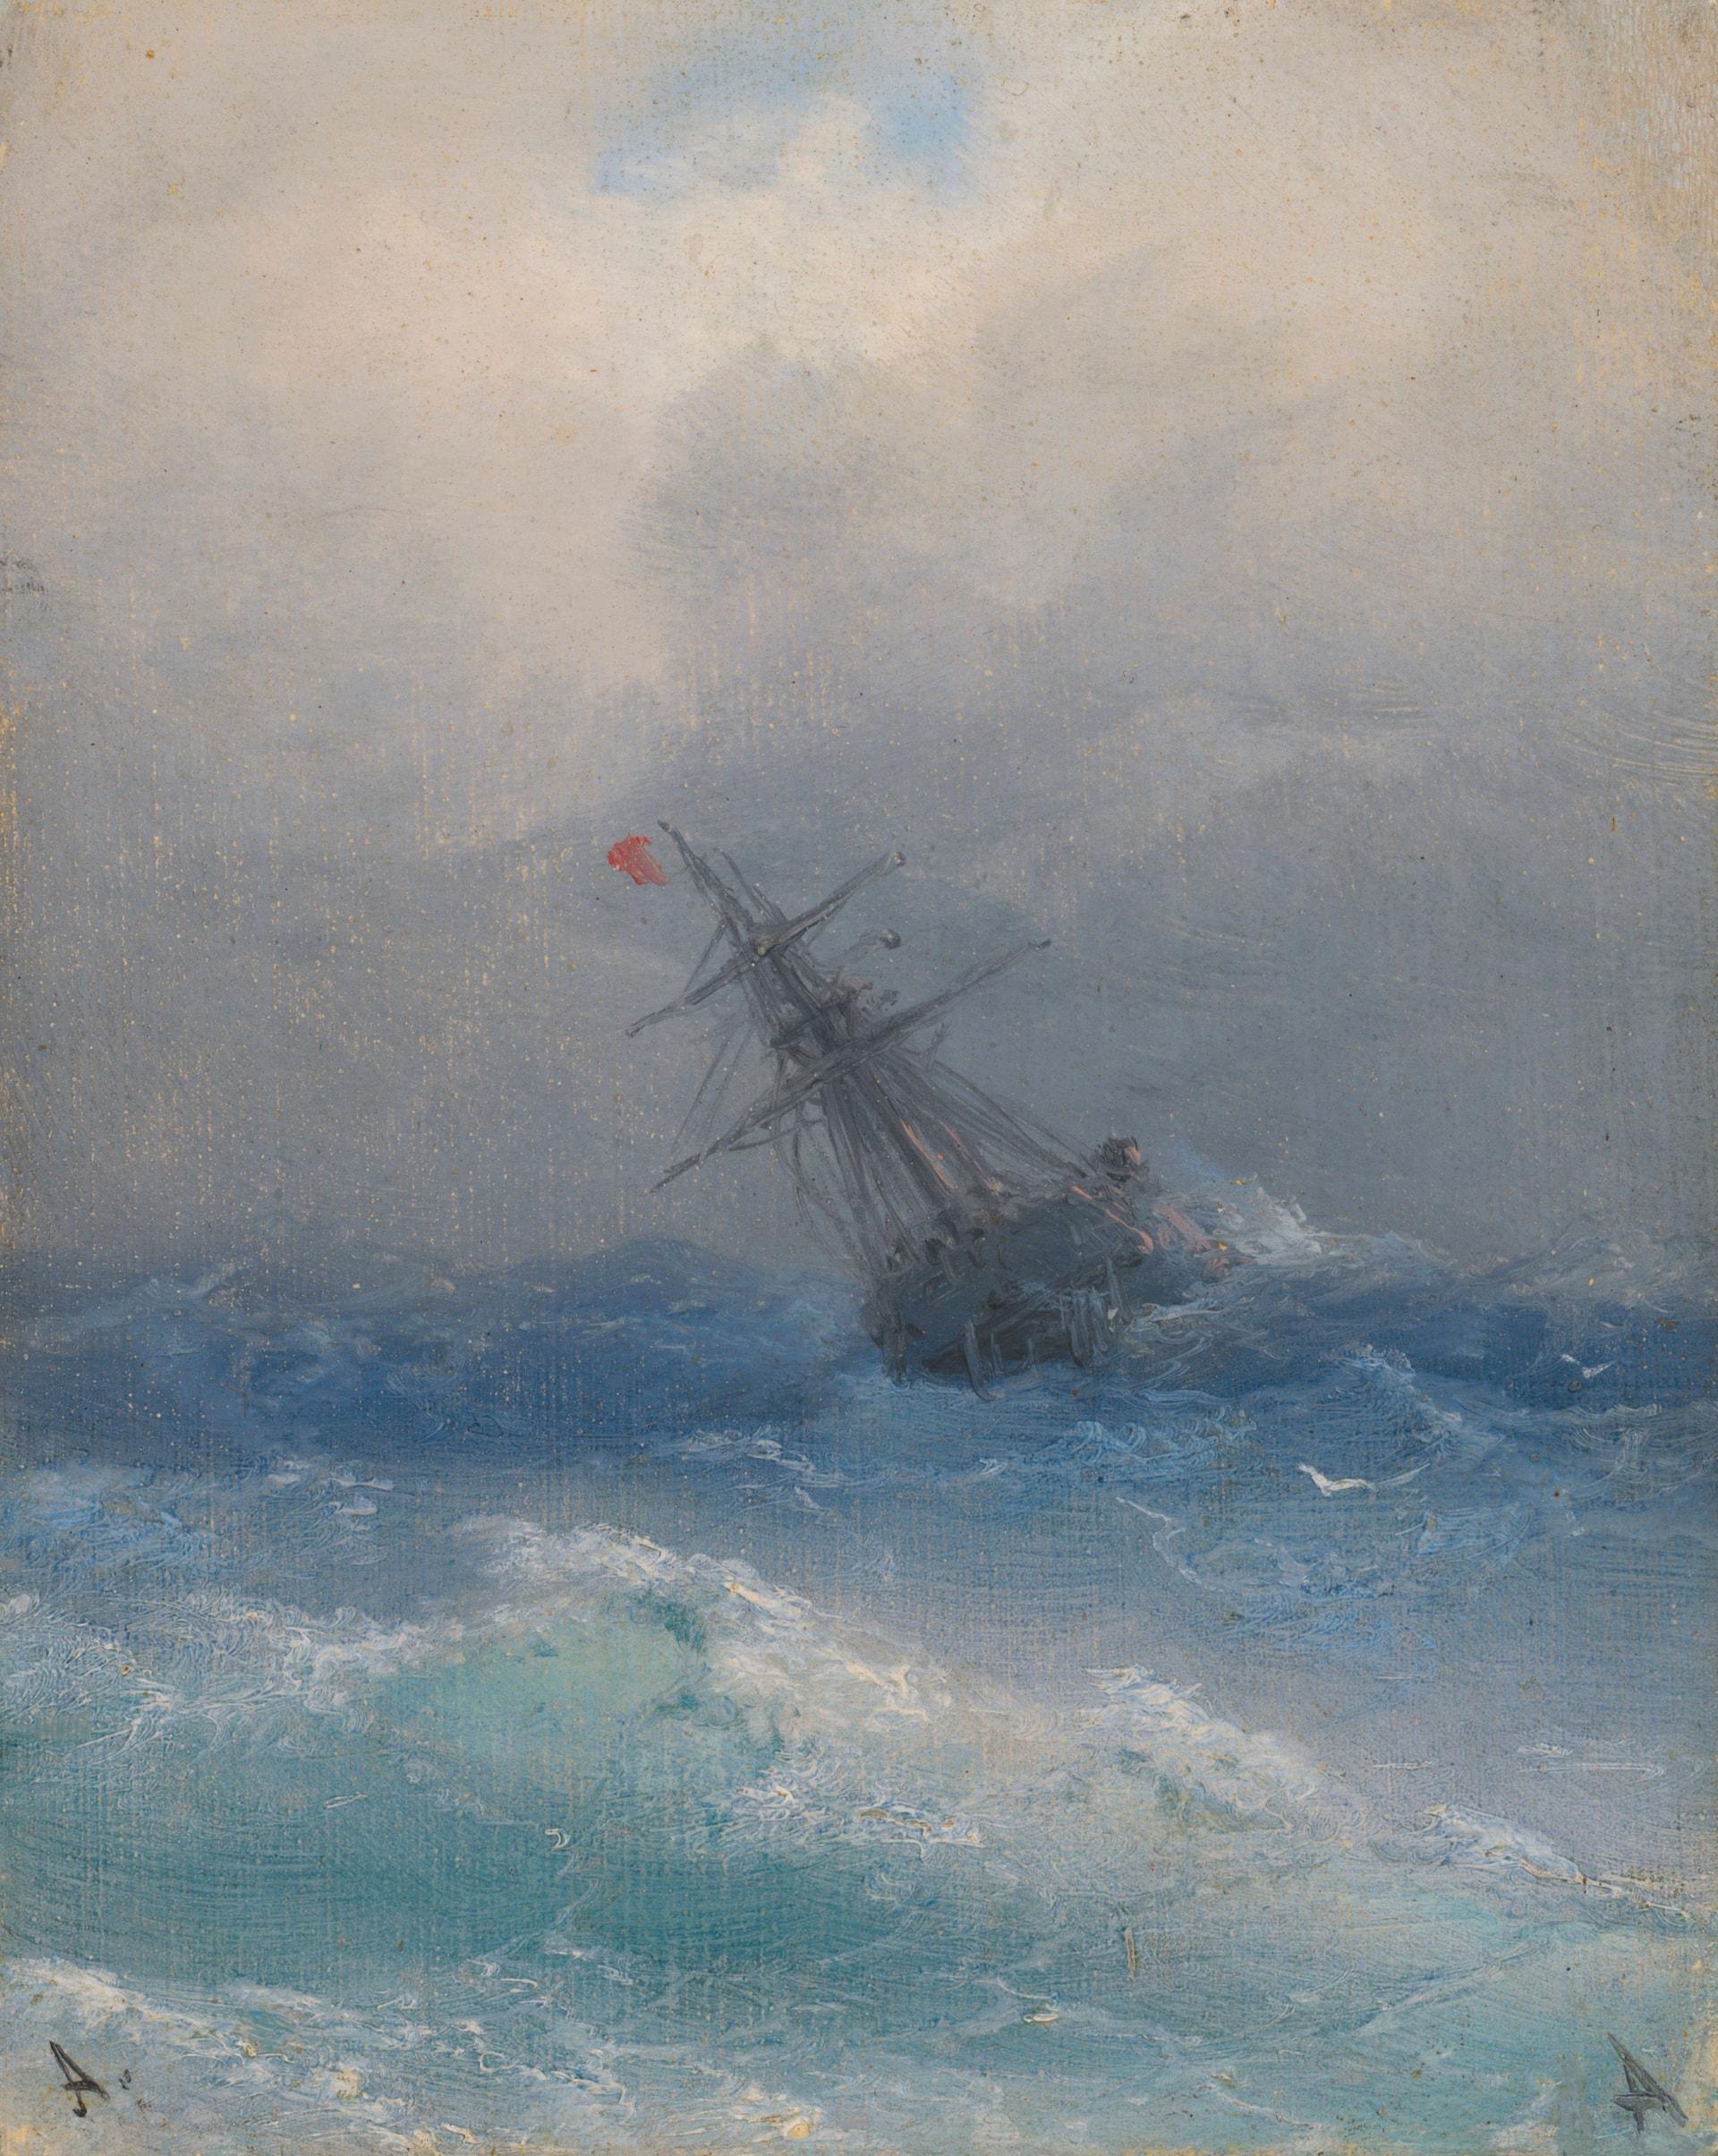
“A tall ship heels over in a storm at sea, camera holding steady as the waves rise.”